Frontier Spatial Intelligence, GPU Infrastructure & Generative 3D Systems
Graphic AI is an artificial intelligence company specializing in multimodal foundation model research and real-world industrial deployment, encompassing multimodal model R&D, inference optimization, enterprise private & on-premises deployment, and high-performance GPU compute cluster services.
算力和 GPU 算力租赁以及私有化部署服务
提供新一代 NVIDIA Blackwell B300 高性能 GPU 服务器与专属集群租赁;并提供硬件级数据隐私保护的本地私有化整机托管与主流大模型(DeepSeek、GLM、Kimi)定制落地。
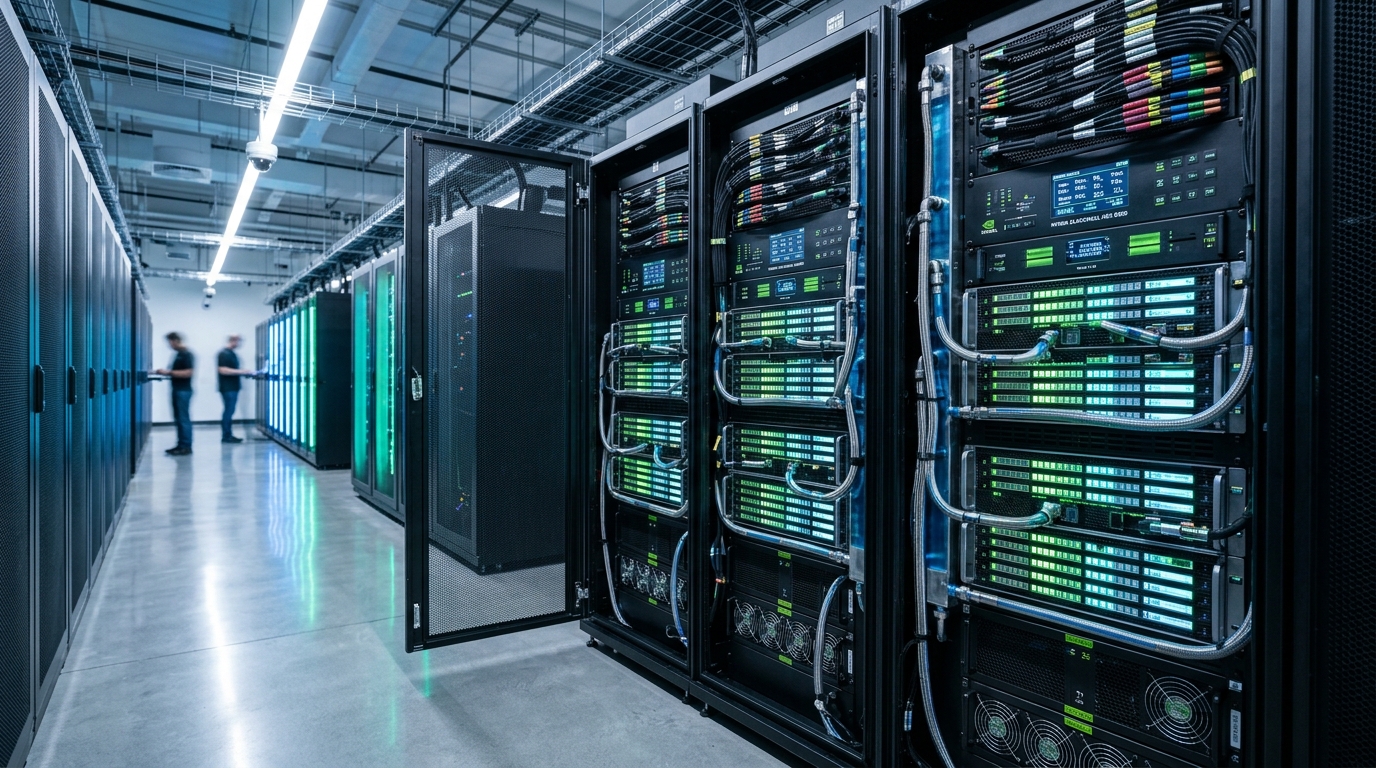
GPU Server & Cluster Leasing (NVIDIA B300)
Providing next-generation NVIDIA Blackwell B300 high-performance servers and dedicated multi-node cluster leasing solutions, featuring 288GB HBM3e VRAM and 8.0 TB/s bandwidth per GPU with 3.2Tbps Quantum-2 InfiniBand non-blocking interconnect for large-scale MoE model training and high-throughput inference.
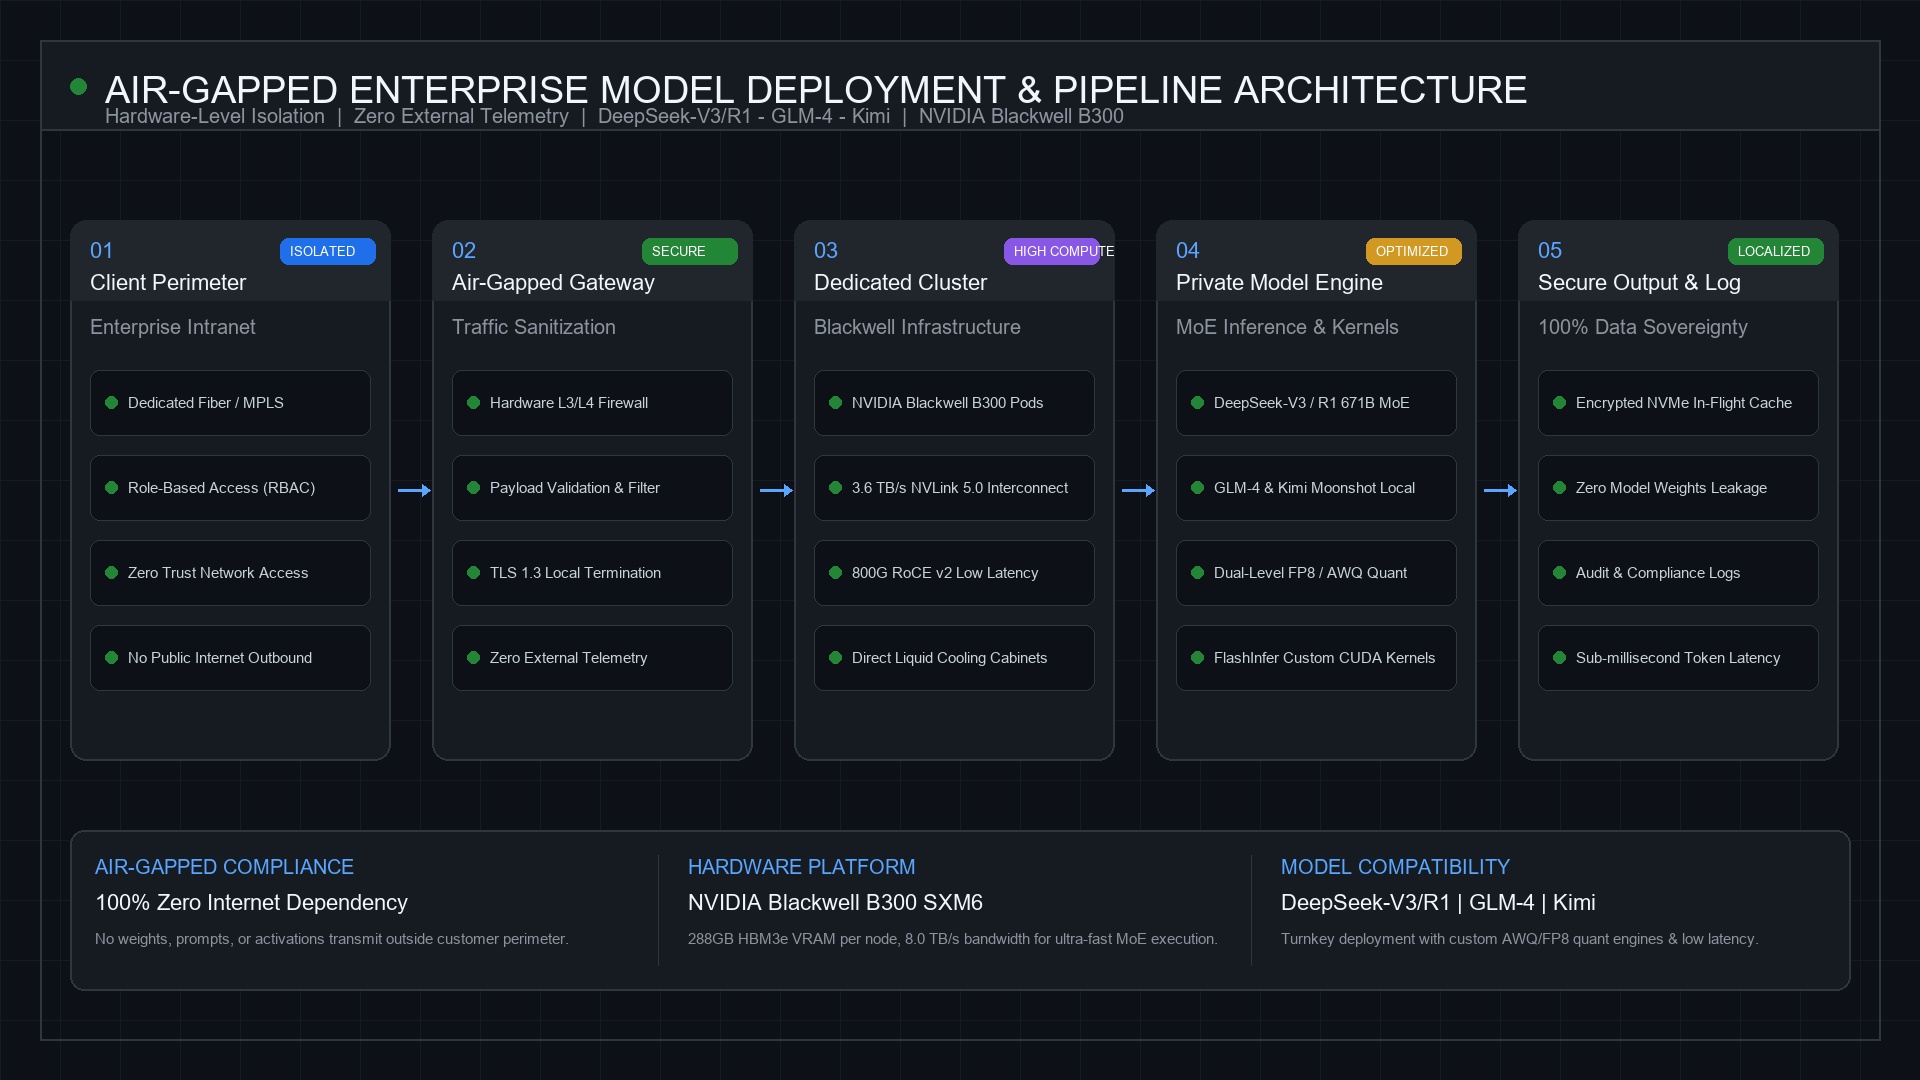
Private On-Premises & Dedicated Colocation Deployment
Providing enterprise turnkey colocation and on-premises private deployment with hardware-level data privacy. Operating in 100% air-gapped physical isolation with zero telemetry, clients can select proprietary models (such as DeepSeek, GLM, Kimi, etc.) with local quantization and kernel optimization to ensure absolute security of proprietary weights and sensitive data.
图形学相关产品和技术解决方案
自主研发先进的 3D 生成模型,具备原生四边面拓扑、解耦 PBR 材质贴图、自动骨骼绑定蒙皮与大模型驱动 Blender 分步建模能力;并提供以动画风格为主的超大世界与 3A 游戏实机图形学管线解决方案。
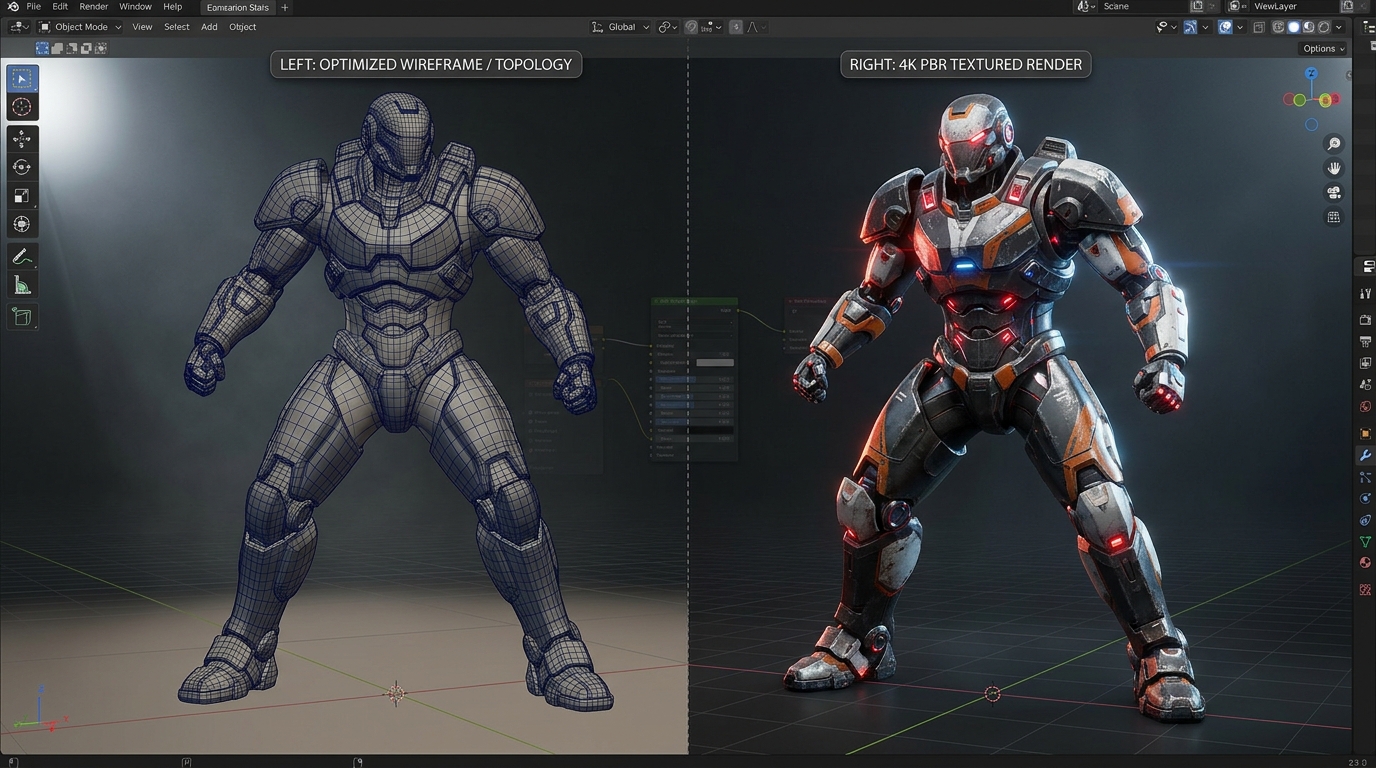
Advanced 3D Asset Generative Model
Proprietary multimodal 3D asset foundation model generating production-ready game and VFX assets from text prompts, single images, or concept turnaround sketches. Generates rapid draft previews in 10–15 seconds and high-fidelity production meshes in 1–2 minutes, delivering native quad-dominant edge-loop topology, 4K decoupled PBR textures, custom polygon counts, and automated skeletal rigging with skinning. Also supports language-model-driven step-by-step procedural modeling in Blender for seamless DCC and game engine workflows.
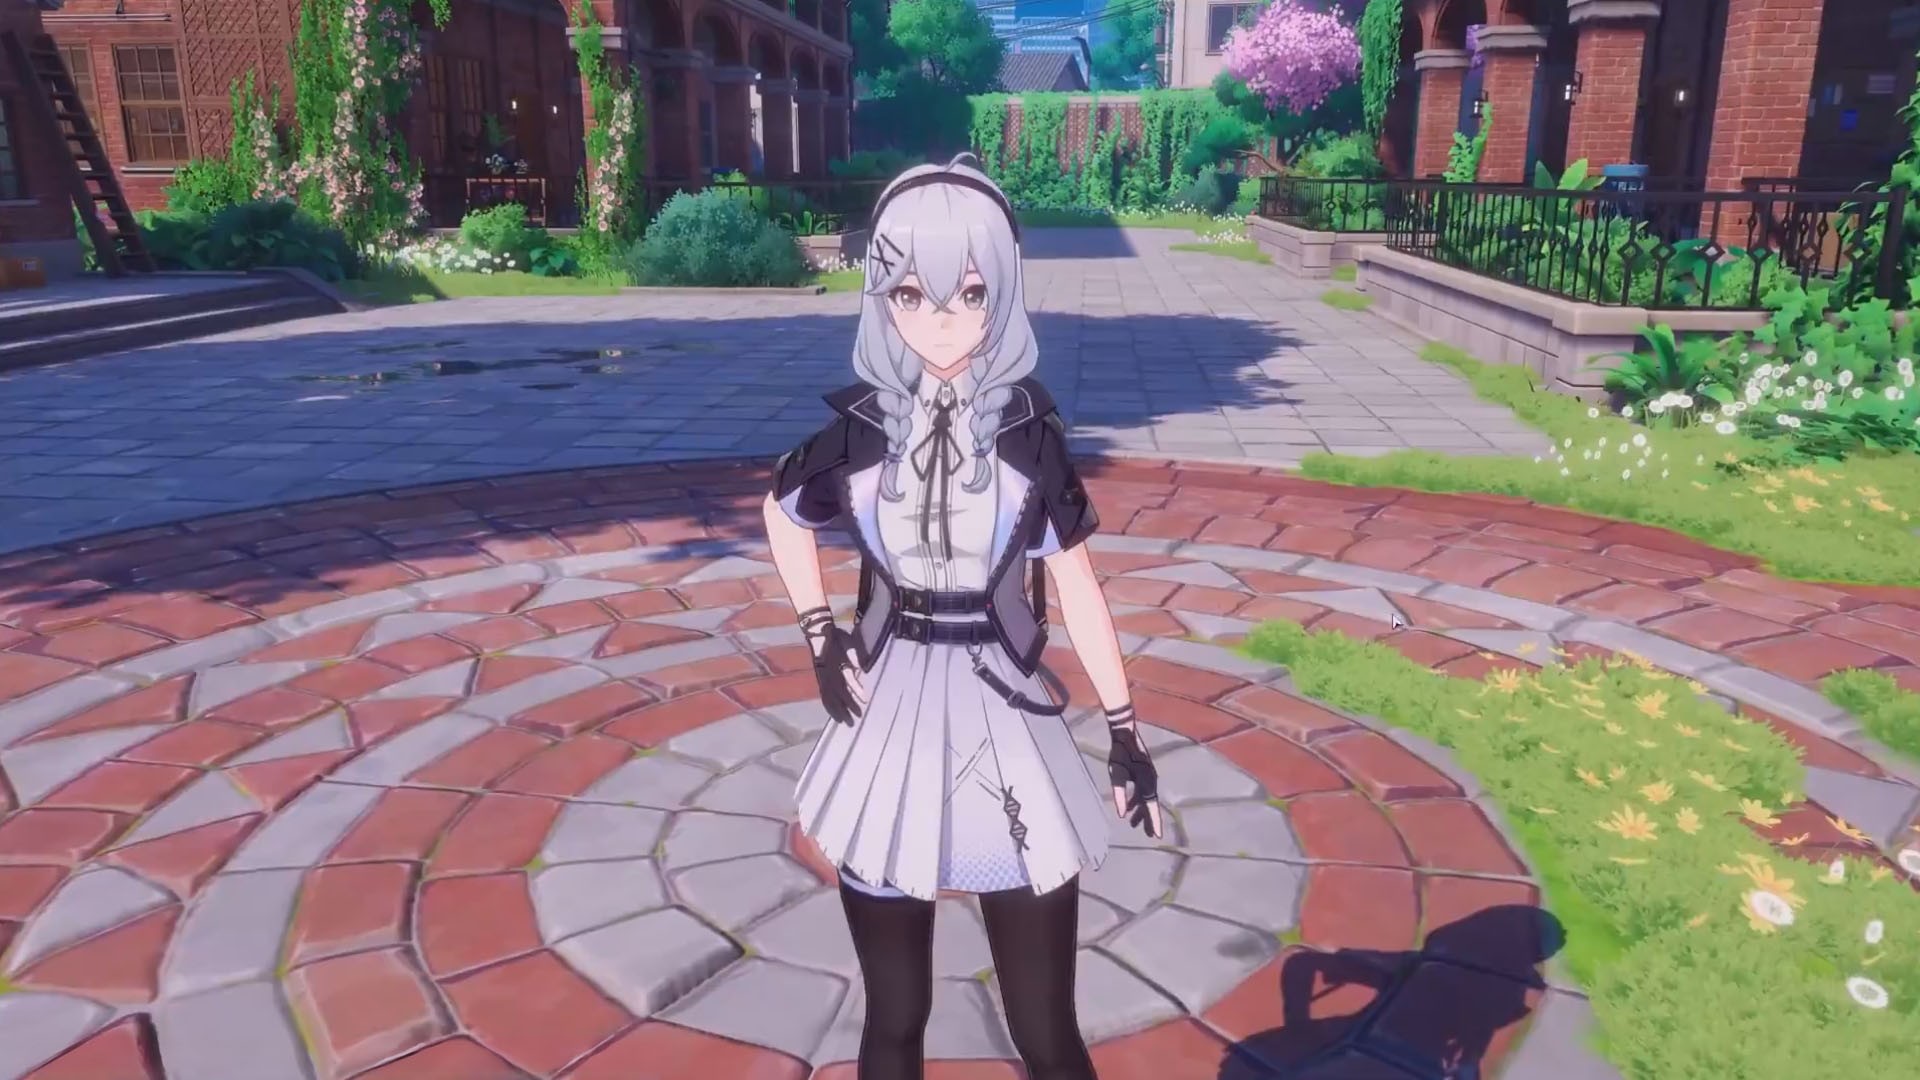
Stylized Animation Rendering & Massive Open-World Game Solutions
Dedicated stylized animation rendering and graphics engineering solutions for massive open-world games. Features a high-fidelity stylized non-photorealistic rendering (NPR) pipeline with dynamic toon lighting and contour ink passes, paired with engine-level pipeline optimization, hierarchical LOD (HLOD) streaming, and custom shader development for massive open-world AAA game productions.
NVIDIA Blackwell B300 MoE Inference & Kernel Matrix
Real-world engineering metrics derived from DeepSeek MoE deployment traces (DeepInfra production profiles) running on NVIDIA B300 (288GB HBM3e) nodes.
Per-chip generation throughput on DeepSeek MoE under production concurrency (3.8x+ vs Hopper H100).
NVFP4 GEMM kernel fusion and DeepEP communication overlap eliminate dispatch stalls, driving TTFT < 160ms.
288GB capacity fits MoE weights with low TP, leaving 200GB+ for native 128K context KV cache without offloading.
Extreme single-GPU density and efficient MoE routing cut hardware count and infrastructure TCO by 75% vs Hopper.
Get in Touch
If you have inquiries regarding GPU server leasing, private model deployment, 3D asset generation, or computer graphics, feel free to contact us.